// guides · 54 articles
Guides
Original, hands on guides from the TrueIQ editors: comparisons, “best tool for the job” roundups and plain English explainers.
Explainers · 10 min readListen
What Is Answer Completeness in RAG Evaluation?
What is answer completeness in RAG evaluation? The share of key facts from a reference answer that a response covers, and how Azure, Bedrock and Ragas score it.
How to · 10 min readListen
How to Use LangSmith with LangGraph (2026)
How to use LangSmith with LangGraph: set four environment variables, read node traces and threads, then score your graph and single nodes on a dataset.
Comparisons · 9 min readListen
LiveBench vs Artificial Analysis: Key Differences
LiveBench vs Artificial Analysis: how the two AI leaderboards differ on tasks, grading, weighting and cost, why their rankings disagree, and when to trust each.
Comparisons · 10 min readListen
Inspect AI vs DeepEval: Which Should You Use?
Inspect AI vs DeepEval in 2026: how the two open source eval frameworks differ on who runs the model, scoring, agents, sandboxes, CI and which team each one suits.
Explainers · 10 min readListen
What Is Claudish? Why AI Text Is Hard to Read
What is Claudish? The dense style of AI coding agents, what a new study found about why AI text is hard to read, and what it means for spotting AI writing.
Explainers · 9 min readListen
Is LangSmith API Free? Keys, Limits and Costs
Is LangSmith API free? Yes: API keys and the REST API cost nothing, and the Developer plan covers 5,000 traces a month. See key types, limits and overage costs.
Explainers · 9 min readListen
Is Langfuse Free for Commercial Use? (2026)
Is Langfuse free for commercial use? Yes: the MIT core can be self hosted in paid products at no cost. See what needs a license key and when the cloud bills.
How to · 8 min readListen
How to Use the MMLU Benchmark, Step by Step
How to use MMLU benchmark runs: pick the right variant, run it with lm-evaluation-harness or Inspect, smoke test the format, and read the score honestly.
Explainers · 6 min readListen
How Does Turnitin Detect AI? What the Score Means
How does Turnitin detect AI? It scores overlapping prose segments by sentence. What it skips, why 1 to 19 percent shows an asterisk, and what to do if flagged.
Explainers · 9 min readListen
FrontierCode Benchmark Explained: How It Scores
The FrontierCode benchmark explained: how Cognition grades whether maintainers would merge AI code, what Main and Diamond mean, and how to read the leaderboards.
Leaderboards · 9 min readListen
Coding Agent Benchmark Rankings (October 2026)
Coding agent benchmark rankings from SWE-Bench Pro, FrontierCode, Terminal-Bench and the Artificial Analysis index, with sourced scores, dates and why they differ.
How to · 10 min readListen
How to Detect AI Writing: A Step by Step Guide
How to detect AI writing: read for the patterns, check facts and sources, run two detectors, ask for drafts, then talk to the writer. A careful method, free.
Comparisons · 9 min readListen
Datadog LLM Observability vs Langfuse (2026)
Datadog LLM Observability vs Langfuse: how each bills (LLM spans vs units), retention, self hosting, evals and setup, with worked cost examples for 2026.
Explainers · 9 min readListen
Artificial Hivemind: Why AI Models Sound Alike
The Artificial Hivemind paper explained: why AI models give the same answers, what Infinity-Chat and NoveltyBench measure, and how to test output diversity yourself.
Comparisons · 10 min readListen
Originality.ai vs GPTZero: Which Should You Use?
Originality.ai vs GPTZero in 2026: free limits, prices, what the Epoch AI test found on human and AI text, and which detector fits publishers or teachers.
Comparisons · 10 min readListen
MMLU vs GPQA: Key Differences and Which to Use
MMLU vs GPQA explained: broad exam recall versus expert written science questions, why GPQA scores run lower, and which benchmark still means anything in 2026.
Explainers · 9 min readListen
LLM Confidence Scores: Can You Trust Them?
Can you trust an LLM confidence score? What verbalized scores, logprobs and sampling measure, what 2026 calibration research shows, and how to set safe thresholds.
Explainers · 9 min readListen
What Is Faithfulness in RAG Evaluation?
What is faithfulness in RAG evaluation? The share of an answer's claims backed by the retrieved context, and how Ragas, DeepEval, TruLens and HHEM score it.
Explainers · 7 min readListen
RAID Benchmark: How to Read the AI Detector Board
The RAID benchmark tests AI text detectors on 6 million samples with attacks. What it measures, how to read the leaderboard, and why 99 percent scores mislead.
How to · 8 min readListen
How to Take a Coding Test: Step by Step
How to take a coding test: check your setup, read every task, submit a correct solution early, then test edge cases and speed, using HackerRank and Codility rules.
Explainers · 10 min readListen
GDPval Benchmark Explained: Tasks, Scores, Limits
The GDPval benchmark tests AI on real work from 44 occupations. How tasks and grading work, how to read the GDPval-AA leaderboard, and what it misses.
Comparisons · 7 min readListen
MMLU vs SWE-bench: Which Should You Use?
MMLU vs SWE-bench explained: what each measures, why the scores are not comparable, and which benchmark to trust for knowledge vs coding agents in 2026.
How to · 9 min readListen
How to Evaluate LLM Model Performance
How to evaluate LLM model performance before you pick one: build a task test set, fix settings, add error bars, test prompt sensitivity, then weigh cost.
Explainers · 8 min readListen
ChatGPT Watermark: How OpenAI's textGrain Works
Does ChatGPT have a watermark? In the EU, yes: OpenAI's textGrain hides a pattern in word choices. How it works, who can detect it, and what it can't prove.
Explainers · 10 min readListen
What Is AI Detection? A Plain English Guide
What is AI detection? A plain English guide to how AI detection software works, what an AI detection report shows, its limits and Google Classroom options.
· updated
Comparisons · 9 min readListen
MMLU vs MMLU Pro: Key Differences and Which to Use
MMLU vs MMLU Pro explained: how the 4 option and 10 option benchmarks differ, why their scores aren't comparable, and which one to trust for LLMs in 2026.
Explainers · 7 min readListen
AI Model Fingerprinting Explained
AI model fingerprinting embeds ownership signals in LLMs. How the Fingerprinting Leaderboard works, SaTML 2026 findings, and how it differs from SynthID.
Comparisons · 10 min readListen
Pangram vs Turnitin: Which Should You Use?
Pangram vs Turnitin in 2026: freemium plus LMS vs campus only AI detection, what the Springer study found, and which tool fits schools, teachers, and students.
· updated
Best of · 8 min readListen
Best Free AI Detector in 2026: Top Picks
Best free AI detector in 2026: Pangram, GPTZero, ZeroGPT and Originality.ai free limits, who each fits, and how to use scores without false accusations.
· updated
Comparisons · 10 min readListen
Originality.ai vs Turnitin: Which to Use?
Originality.ai vs Turnitin in 2026: 100 free credits vs campus licenses, how AI Allowance differs from Turnitin scores, and what peer reviewed studies found.
· updated
Explainers · 9 min readListen
AI Agent Observability: What It Is and Top Tools
AI agent observability explained: trace tool loops, permissions and memory, the six PAI telemetry gaps, and which tools fit, from Langfuse to Datadog.
· updated
Comparisons · 7 min readListen
OpenAI Evals vs DeepEval: Which to Use?
OpenAI Evals vs DeepEval in 2026: platform shutdown timeline, DeepEval's pytest CI metrics, multiprovider support, and Promptfoo as the migration path.
How to · 7 min readListen
How to Use Originality.ai for Free
How to use Originality.ai for free in 2026: 100 free credits per account (about 10,000 words), how credits burn by model, privacy notes and how to read AI scores.
· updated
How to · 8 min readListen
How to Use Pangram on Substack
How to use Pangram on Substack: Scan for AI text on web and iOS, creator controls, July 2026 limits, and how to read the human vs AI assisted estimate.
· updated
Explainers · 7 min readListen
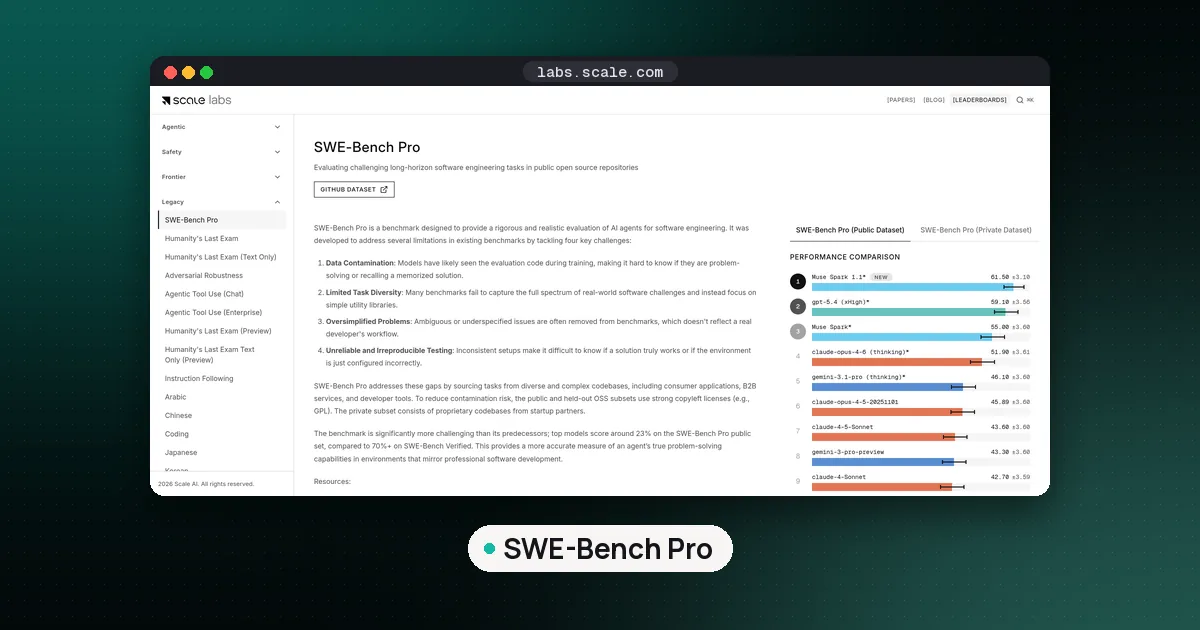
SWE-Bench Pro Explained: V1, V2, Scores
SWE-Bench Pro explained: how the Scale AI coding benchmark differs from Verified, what changed in V2, and how to read public and private leaderboard scores.
Comparisons · 10 min readListen
Pangram vs GPTZero: Which Should You Use?
Pangram vs GPTZero in 2026: free plans, Pangram 4 and GPTZero 4o, what independent studies found, and which AI detector fits educators, publishers, and teams.
· updated
How to · 8 min readListen
SynthID Detector: How to Check for AI Watermarks
Google's SynthID Detector is now open to everyone. How to check images, video and audio for its AI watermark, what results mean, the limits, and alternatives.
Explainers · 8 min readListen
HLE Diamond Leaderboard and Scores (October 2026)
HLE Diamond leaderboard and scores for October 2026: the 1,000 question Humanity's Last Exam subset, Scale and lastexam.ai results, with and without tools.
· updated
Explainers · 9 min readListen
Deepfake Detection: Hive, SynthID and C2PA Compared
Deepfake detection in 2026: how Hive's deepfake detector, SynthID watermarks and C2PA Content Credentials work, how accurate they are, and a checklist.
· updated
Explainers · 9 min readListen
Are AI Detectors Accurate? What 2026 Studies Show
Are AI detectors accurate? What 2026 studies found on Turnitin, GPTZero, Originality.ai and Pangram, false positives, edited text, and what to do if flagged.
· updated
Explainers · 10 min readListen
LLM Benchmarks Explained: What the Scores Mean
LLM benchmarks explained: what MMLU, GPQA Diamond, Humanity's Last Exam, SWE-bench and ARC-AGI measure, why scores saturate, and how to spot contamination.
· updated
Best of · 9 min readListen
Best LLM Observability Tools in 2026, Compared
The best LLM observability tools in 2026 compared: Langfuse, LangSmith, Phoenix, Opik, Weave and more, with licenses, self hosting and who now owns what.
· updated
Explainers · 8 min readListen
Prompt Injection Attacks: Examples and How to Test
What a prompt injection attack is, direct and indirect examples, why there is no complete fix, and how to test your LLM app with Promptfoo, garak and PyRIT.
· updated
Explainers · 7 min readListen
RAG Evaluation Metrics: Ragas vs DeepEval vs TruLens
RAG evaluation metrics explained: faithfulness, relevancy, context precision and recall, which need a reference, and how Ragas, DeepEval and TruLens differ.
· updated
Explainers · 6 min readListen
LLM Hallucination Detection: Methods and Tools
How LLM hallucination detection works in 2026: faithfulness checks, detector models like HHEM, self consistency and semantic entropy, and the tools to use.
· updated
Comparisons · 10 min readListen
GPTZero vs Turnitin: Which AI Detector Is Better?
GPTZero vs Turnitin in 2026: who can use each, what scores mean, what independent studies found, GPTZero 4o and Turnitin's 2026 model updates, and which fits.
· updated
Best of · 7 min readListen
Best LLM Evaluation Frameworks in 2026, Compared
The best LLM evaluation frameworks in 2026: Promptfoo, DeepEval, Ragas, Inspect and TruLens for apps, plus lm-evaluation-harness and HELM for model benchmarks.
· updated
Comparisons · 7 min readListen
LLM Red Teaming Tools: Promptfoo, garak, PyRIT
The best LLM red teaming tools in 2026 compared: Promptfoo, garak, PyRIT, DeepTeam and Giskard, with licenses, first commands and OWASP LLM Top 10 coverage.
Comparisons · 7 min readListen
LLM Leaderboards Compared: Which Ones to Trust
Every major LLM leaderboard compared: how Arena, Artificial Analysis, LiveBench, SEAL, Epoch AI and Vellum score models, and where each one can mislead you.
Explainers · 7 min readListen
LLM Evaluation Metrics: What to Measure and How
The LLM evaluation metrics that matter in 2026: exact match, BLEU, ROUGE, BERTScore, pass@k, LLM judge rubrics, RAG and safety metrics, and when to use each.
Explainers · 7 min readListen
LLM as a Judge: How It Works and When to Trust It
LLM as a judge explained: how model graders work, the biases that skew them, how to validate one against human labels, and which open source tools to use.
Comparisons · 7 min readListen
Langfuse vs LangSmith: Which Should You Use?
Langfuse vs LangSmith in 2026: open source license, self hosting, pricing, retention, framework fit and migration tips, so you can pick the right LLM tracer.
Comparisons · 6 min readListen
Langfuse vs Arize Phoenix: Which to Self Host?
Langfuse vs Arize Phoenix in 2026: licenses, self hosting stacks, features, managed pricing, new owners and which open LLM tracing tool fits your team best.
How to · 9 min readListen
How to Evaluate LLM Applications (2026 Guide)
How to evaluate LLM applications step by step: error analysis, code checks, calibrated LLM judges, CI gates and production sampling, with tools for each stage.