




// field guide
A practical guide to measuring intelligence: artificial and human
You cannot improve what you do not measure, and in AI measurement has become its own discipline. TrueIQ is a directory for the tools that do that measuring. On one side are evaluation frameworks, benchmarks and observability platforms that tell builders whether a language model or agent is accurate, safe and worth its cost. On the other are assessment and psychometric platforms that measure human skills, aptitude and cognition. Both ask the same question: how do we know how capable something really is?
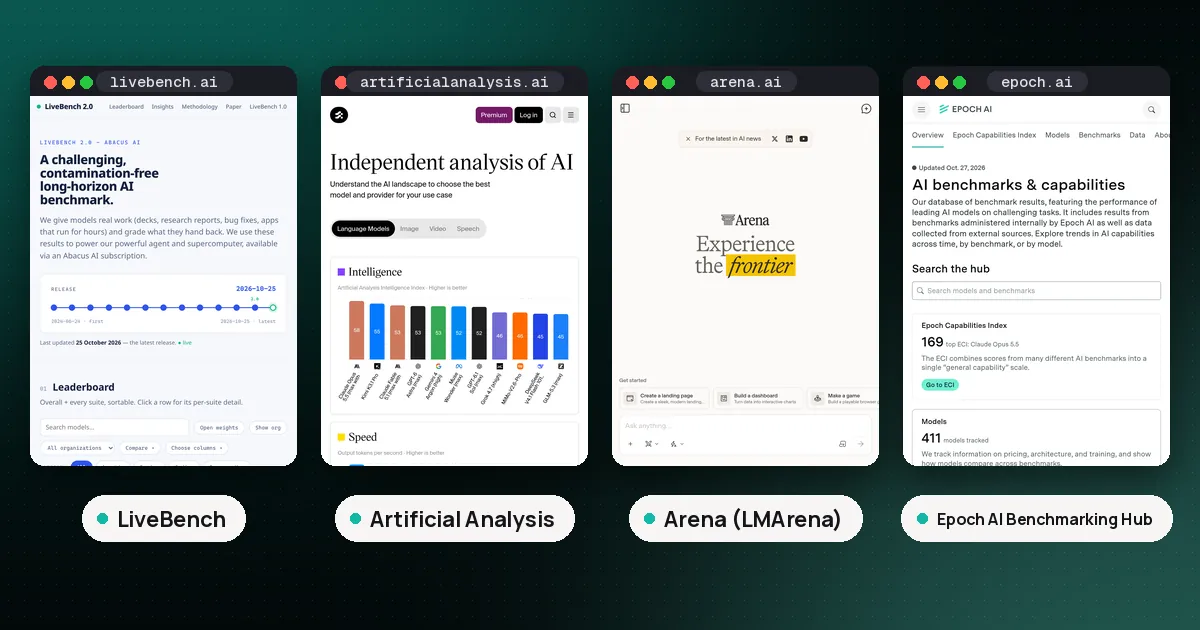
If you build with LLMs, start with the evals and benchmarks categories. Benchmarks such as MMLU, GPQA, SWE-bench and ARC-AGI are the shared yardsticks the field reports against. Academic harnesses such as EleutherAI's lm-evaluation-harness, Stanford's HELM and Hugging Face's lighteval run standard benchmarks reproducibly. Application level tools like Promptfoo, DeepEval, Ragas and Braintrust let you write tests for your own prompts and pipelines, run them in CI and catch regressions before users do. Leaderboards (Arena, Artificial Analysis, LiveBench, SEAL and others) help you shortlist models, but each measures something specific, from human preference to contamination resistant accuracy to tokens per second, so compare like with like.
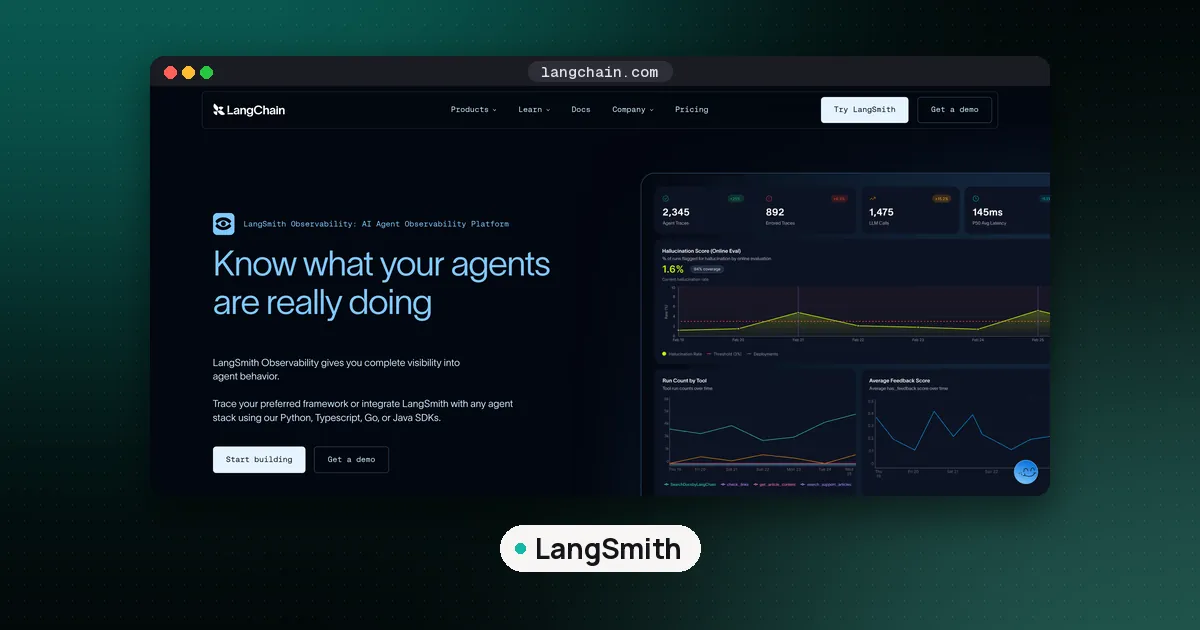
Once an application is live, observability takes over. Platforms such as Langfuse, LangSmith, Arize Phoenix, Helicone and Opik trace every call, record latency and cost, and attach evaluation scores to real traffic. Good evaluation is continuous: the best teams feed production failures back into their test sets, and red teaming tools such as garak and PyRIT probe for jailbreaks and unsafe behaviour before attackers do. We also list integrity tools that estimate whether writing was AI generated; they are useful signals for educators and publishers but can produce false positives, so they should inform judgement rather than replace it.
The human side of TrueIQ covers assessment and psychometrics: classroom grading, technical hiring tests, aptitude and IQ style tests and research grade cognitive batteries. These tools are not medical devices, and no online test captures the whole of a person's intelligence; we describe what each product does, link to its official site and leave clinical claims to qualified professionals. The live feed below brings in new benchmark and evaluation papers from arXiv and Hugging Face, plus discussion from Hacker News.